Keep your articles cited in AI answers without feeding training crawlers
Publishers want AI answers to cite and link their stories, not to have the archive copied into training sets. Velbrake splits the bots: training crawlers are refused on the server, search and assistant bots keep reading, and impostors using a crawler's name are blocked.
How publishing teams use Velbrake
- Install the free plugin and leave the default policy on.
- Enter your host's price per GB to see each bot's cost over 30 days.
- With Pro, protect paths such as /premium/ or the archive from every bot you choose.
- Publish llms.txt from Pro to point AI assistants at your best pages.
If the site sits behind a full-page cache or CDN, add matching bot rules there; cached pages never reach WordPress.
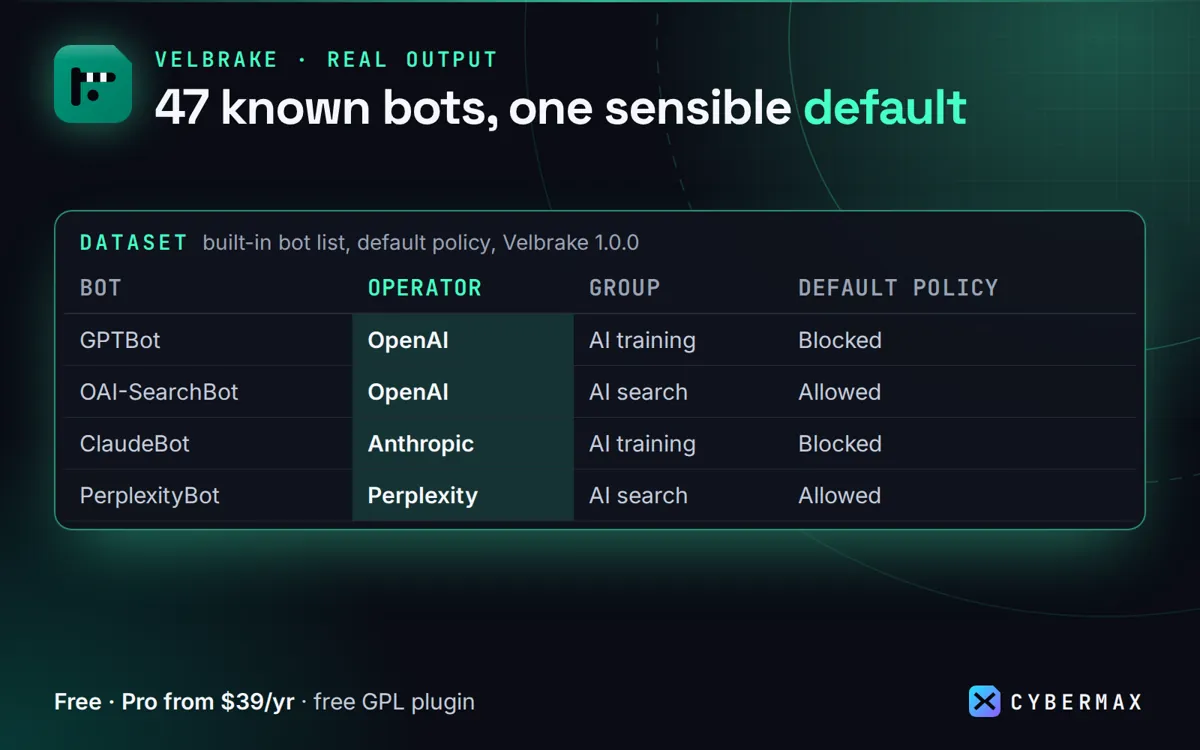
Built-in bot list and default policy, Velbrake 1.0.0
| Bot | Operator | Group | Default policy | Identity check |
|---|---|---|---|---|
| GPTBot | OpenAI | AI training | Blocked | OpenAI IP list |
| OAI-SearchBot | OpenAI | AI search | Allowed | OpenAI IP list |
| ClaudeBot | Anthropic | AI training | Blocked | Anthropic IP list |
| PerplexityBot | Perplexity | AI search | Allowed | Perplexity IP list |
| Bytespider | ByteDance | AI training | Blocked | user agent |
Source: products/velbrake/store/listing.json (built-in bot list and default policy of Velbrake 1.0.0).
FAQ
Can I block one AI company completely?
Yes; switch each of its bots (training and search) to blocked.
Does it replace robots.txt?
No, it adds to it. Keep your robots.txt rules; Velbrake also enforces them on the server for requests that reach WordPress.
Velbrake: full guide with prices and alternatives · All use cases · Store